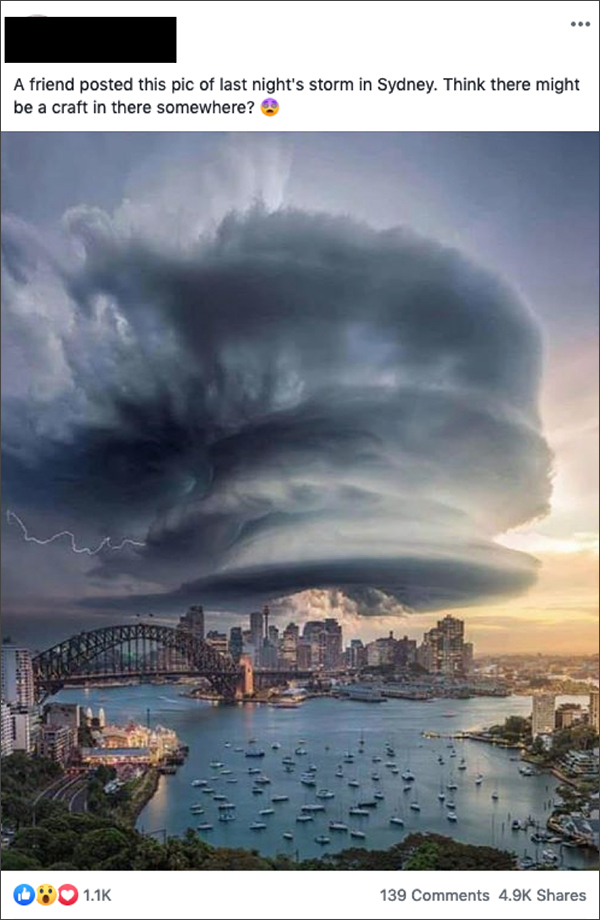
We’ve all seen the images scrolling through our social media feeds — the improbably large pet that dwarfs the human sitting beside it; the monstrous stormcloud ominously bearing down on a city full of people; the elected official who says or does something outrageous (and outrageously out of character). We might stop mid-scroll and do a double-take, occasionally hit “like” or “share,” or dismiss the content as fake news. But how do we as consumers of information determine what is real and what is fake?
Freakishly large Fido may be fake news — sorry! — but this isn’t: A team of researchers led by professor Franziska Roesner, co-director of the Allen School’s Security and Privacy Research Laboratory, conducted a study examining how and why users investigate and act on fake content shared on their social media feeds. The project, which involved semi-structured interviews with more than two dozen users ranging in age from 18 to 74, aimed to better understand what tools would be most useful to people trying to determine which posts are trustworthy and which are bogus.
In a “think aloud” study in the lab, the researchers asked users to provide a running commentary on their reaction to various posts as they scrolled through their social feeds. Their observations provided the team with insights into the thought process that goes into a user’s decision to dismiss, share, or otherwise engage with fake content they encounter online. Unbeknownst to the participants, the researchers deployed a browser extension that they had built which randomly layered misinformation posts previously debunked by Snopes.com over legitimate posts shared by participants’ Facebook friends and accounts they follow on Twitter.
The artificial posts that populated users’ feeds ranged from the sublime (the aforementioned giant dog), to the ridiculous (“A photograph shows Bernie Sanders being arrested for throwing eggs at civil rights protesters”), to the downright hilarious (“A church sign reads ‘Adultery is a sin. You can’t have your Kate and Edith too’”). As the participants scrolled through the mixture of legitimate and fake posts, Allen School Ph.D. student Christine Geeng and her colleagues would ask them why they chose to engage with or ignore various content. At the end of the experiment, the researchers pointed out the fake posts and informed participants that their friends and contacts had not really shared them. Geeng and her colleagues also noted that participants could not actually like or share the fake content on their real feeds.
“Our goal was not to trick participants or to make them feel exposed,” explained Geeng, lead author of the paper describing the study. “We wanted to normalize the difficulty of determining what’s fake and what’s not.”
Participants employed a variety of strategies in dealing with the misinformation posts as they scrolled through. Many posts were simply ignored at first sight, whether because they were political in nature, required too much time and effort to investigate, or the viewer was simply disinterested in the topic presented. If a post caught their attention, some users investigated further by looking at the name on the account that appeared to have posted it, or read through comments from others before making up their own minds. For others, they might click through to the full article to check if the claim was bogus — such as in the case of the Bernie Sanders photo, which was intentionally miscaptioned in the fake post. Participants also self-reported that, outside of a laboratory setting, they might consult a fact-checking website like Snopes.com, see if trusted news sources were reporting on the same topic, or seek out the opinions of family members or others in their social circle.
The researchers found that users were more likely to employ such ad hoc strategies over purpose-built tools provided by the platforms themselves. For example, none of the study participants used Facebook’s “i” button to investigate fake content; in fact, most said they were unaware of the button’s existence. Whether a matter of functionality or design (or both), the team’s findings suggest there is room for improvement when it comes to offering truly useful tools for people who are trying to separate fact from fiction.
“There are a lot of people who are trying to be good consumers of information and they’re struggling,” said Roesner. “If we can understand what these people are doing, we might be able to design tools that can help them.”
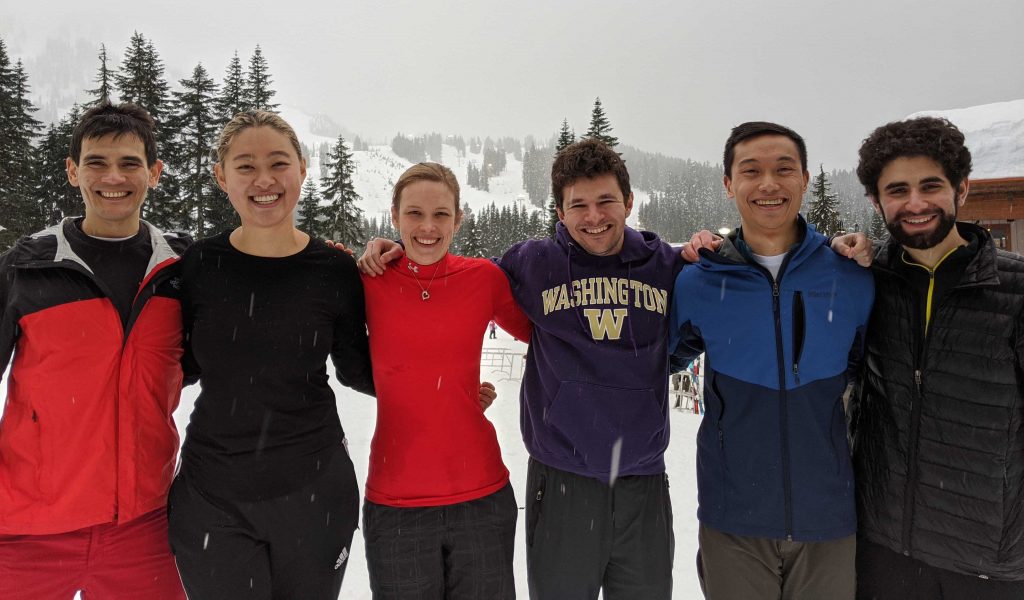
Several members of the Security Lab had a great time at the Allen School’s traditional annual ski day last Friday! We even forged potential new research collaborations during the après-ski 🙂
Congratulations to Security Lab undergraduate Kimberly Ruth for winning a CRA Outstanding Undergraduate Research Award! Kimberly has been doing research in the Security Lab for four years, focused on security and privacy for emerging augmented reality technologies. This is a huge accomplishment and honor — congratulations Kimberly!!
Security and Privacy Lab co-director Professor Franzi Roesner was interviewed on KUOW’s “Primed” Podcast about how smart home technologies can exacerbate existing power dynamics or tensions among home occupants or visitors. Listen to the interview here. Read more about the Security Lab’s work on this topic in several papers:
Genetic genealogy websites enable people to upload their results from consumer DNA testing services like Ancestry.com and 23andMe to explore their genetic makeup, familial relationships, and even discover new relatives they didn’t know they had. But how can you be sure that the person who emails you claiming to be your Uncle Phil really is a long-lost relation?
Through a series of highly-controlled experiments using information from the GEDmatch online database, Allen School alumnus and current postdoctoral researcher Peter Ney (Ph.D., ‘19) and professors Tadayoshi Kohno and Luis Ceze determined that it would be relatively straightforward for an adversary to exploit vulnerabilities in the site’s application programming interface (API) that compromise users’ privacy and expose them to potential fraud. The team demonstrated multiple ways in which they could extract highly personal, potentially sensitive genetic information about individuals on the site — and use existing familial relationships to create false new ones by uploading fake profiles that indicate a genetic match where none exists.
Part of GEDmatch’s attraction is its user-friendly graphical interface, which relies on bars and color-coding to visualize specific genetic markers and similarities between two profiles. For example, the “chromosome paintings” illustrate the differences between two profiles on each chromosome, accompanied by “segment coordinates” that indicate the precise genetic markers that the profiles share. These one-to-one comparisons, however, can be used to reveal more information than intended. It was this aspect of the service that the researchers were able to exploit in their attacks. To their surprise, they were not only able to determine the presence or absence of various genetic markers at certain segments of a hypothetical user’s profile, but to reconstruct 92% of the entire profile with 98% accuracy.
As a first step, Ney and his colleagues created a research account on GEDmatch, to which they uploaded artificial genetic profiles generated from data contained in anonymous profiles from multiple, publicly available datasets designated for research use. By assigning each of their profiles a privacy setting of “research,” the team ensured that their artificial profiles would not appear in public matching results. Once the profiles were uploaded, GEDmatch automatically assigned each one a unique ID, which enabled the team to perform comparisons between a specific profile and others in the database — in this case, a set of “extraction profiles” created for this purpose. The team then performed a series of experiments. For the total profile reconstruction, they uploaded and ran comparisons between 20 extraction profiles and five targets. Based on the GEDmatch visualizations alone, they were able to recover just over 60% of the target profiles’ data. Based on their knowledge of genetics, specifically the frequency with which possible DNA bases are found within the population at a specific position on the genome, they were able to determine another 30%. They then relied on a genetic technique known as imputation to fill in the rest.
Once they had constructed nearly the whole of a target’s profile, the researchers used that information to create a false child for one of their targets. When they ran the comparison between the target profile and the false child profile through the system, GEDmatch confirmed that the two were a match for a parent-child relationship.
While it is true that an adversary would have to have the right combination of programming skills and knowledge of genetics and genealogy to pull it off, the process isn’t as difficult as it sounds — or, to a security expert, as it should be. To acquire a person’s entire profile, Ney and his colleagues performed the comparisons between extraction and target profiles manually. They estimate the process took 10 minutes to complete — a daunting prospect, perhaps, if an adversary wanted to compare a much greater number of targets. But if one were to write a script that automatically performs the comparisons? “That would take 10 seconds,” said Ney, who is the lead author of the paper.
Consumer-facing genetic testing and genetic genealogy are still relatively nascent industries, but they are gaining in popularity. And as the size of the database grows, so does the interest of law enforcement looking to crack criminal cases for which the trail has gone cold. In one high-profile example from last year, investigators arrested a suspect alleged to be the Golden State Killer, whose identity remained elusive for more than four decades before genetic genealogy yielded a breakthrough. Given the prospect of using genetic information for this and other purposes, the researchers’ findings yield important questions about how to ensure the security and integrity of genetic genealogy results, now and into the future.
“We’re only beginning to scratch the surface,” said Kohno, who co-directs the Allen School’s Security and Privacy Research Lab and previously helped expose potential security vulnerabilities in internet-connected motor vehicles, wireless medical implants, consumer robotics, mobile advertising, and more. “The responsible thing for us is to disclose our findings so that we can engage a community of scientists and policymakers in a discussion about how to mitigate this issue.”
Echoing Kohno’s concern, Ceze emphasizes that the issue is made all the more urgent by the sensitive nature of the data that people upload to a site like GEDmatch — with broad legal, medical, and psychological ramifications — in the midst of what he refers to as “the age of oversharing information.”
“Genetic information correlates to medical conditions and potentially other deeply personal traits,” noted Ceze, who co-directs the Molecular Information Systems Laboratory at the University of Washington and specializes in computer architecture research as a member of the Allen School’s Sampa and SAMPL groups. “As more genetic information goes digital, the risks increase.”
Unfortunately for those who are not prone to oversharing, the risks extend beyond the direct users of genetic genealogy services. According to Ney, GEDmatch contains the personal genetic information of a sufficient number and variety of people across the U.S. that, should someone gain illicit possession of the entire database, they could potentially link genetic information with identity for a large portion of the country. While Ney describes the decision to share one’s data on GEDmatch as a personal one, some decisions appear to be more personal — and wider reaching — than others. And once a person’s genetic data is compromised, he notes, it is compromised forever.
So whether or not you’ve uploaded your genetic information to GEDmatch, you might want to ask Uncle Phil for an additional form of identification before rushing to make up the guest bed.
“People think of genetic data as being personal — and it is. It’s literally part of their physical identity,” Ney said. “You can change your credit card number, but you can’t change your DNA.”
The Security and Privacy Research Lab is excited to welcome new PhD student Miranda Wei! Prior to starting her PhD, Miranda worked with Blase Ur at the University of Chicago.
For now, augmented reality remains mostly a solo activity, but soon people might be using the technology in groups for collaborating on work or creative projects.
A few summers ago throngs of people began using the Pokemon Go app, the first mass-market augmented reality game, to collect virtual creatures hiding in the physical world.
For now, AR remains mostly a solo activity, but soon people might be using the technology for a variety of group activities, such as playing multi-user games or collaborating on work or creative projects. But how can developers guard against bad actors who try to hijack these experiences, and prevent privacy breaches in environments that span digital and physical space?
University of Washington security researchers have developed ShareAR, a toolkit that lets app developers build in collaborative and interactive features without sacrificing their users’ privacy and security. The researchers presented their findings Aug. 14 at the USENIX Security Symposium in Santa Clara, California.
“A key role for computer security and privacy research is to anticipate and address future risks in emerging technologies,” said co-author Franziska Roesner, an assistant professor in the Paul G. Allen School of Computer Science & Engineering. “It is becoming clear that multi-user AR has a lot of potential, but there has not been a systematic approach to addressing the possible security and privacy issues that will arise.”
Sharing virtual objects in AR is in some ways like sharing files on a cloud-based platform like Google Drive — but there’s a big difference.
“AR content isn’t confined to a screen like a Google Doc is. It’s embedded into the physical world you see around you,” said first author Kimberly Ruth, a UW undergraduate student in the Allen School. “That means there are security and privacy considerations that are unique to AR.”
For example, people could potentially add virtual inappropriate images to physical public parks, scrawl virtual offensive messages on places of worship or even place a virtual “kick me” sign on an unsuspecting user’s back.
“We wanted to think about how the technology should respond when a person tries to harass or spy on others, or tries to steal or vandalize other users’ AR content,” Ruth said. “But we also don’t want to shut down the positive aspects of being able to share content using AR technologies, and we don’t want to force developers to choose between functionality and security.”
To address these concerns, the team created a prototype toolkit, ShareAR, for the Microsoft HoloLens. ShareAR helps applications create, share and keep track of objects that users share with each other.
Another potential issue with multi-user AR is that developers need a way to signal the physical location of someone’s private virtual content to keep other users from accidentally standing in between that person and their work — like standing between someone and the TV. So the team developed “ghost objects” for ShareAR.
“A ghost object serves as a placeholder for another virtual object. It has the same physical location and rough 3D bulk as the object it stands in for, but it doesn’t show any of the sensitive information that the original object contains,” Ruth said. “The benefit of this approach over putting up a virtual wall is that, if I’m interacting with a virtual private messaging window, another person in the room can’t sneak up behind me and peer over my shoulder to see what I’m typing — they always see the same placeholder from any angle.”
The team tested ShareAR with three case study apps. Creating objects and changing permission settings within the apps were the most computationally expensive actions. But, even when the researchers tried to stress out the system with large numbers of users and shared objects, ShareAR took no longer than 5 milliseconds to complete a task. In most cases, it took less than 1 millisecond.
The team tested ShareAR with three case study apps: Cubist Art (top panel), which lets users create and share virtual artwork with each other; Doc Edit (bottom left panel), which lets users create virtual notes or lists they can share or keep private; and Paintball (bottom right panel), which lets users play paintball with virtual paint. In the Doc Edit app, the semi-transparent gray box in the top left corner represents a “ghost object,” or a document that another user wishes to remain private.Ruth et al./USENIX Security Symposium
“We’ll be very interested in hearing feedback from developers on what’s working well for them and what they’d like to see improved,” Ruth said. “We believe that engaging with technology builders while AR is still in development is the key to tackling these security and privacy challenges before they become widespread.”
Tadayoshi Kohno, a professor in the Allen School, is also a co-author on this paper. This research was funded by the National Science Foundation and the Washington Research Foundation.
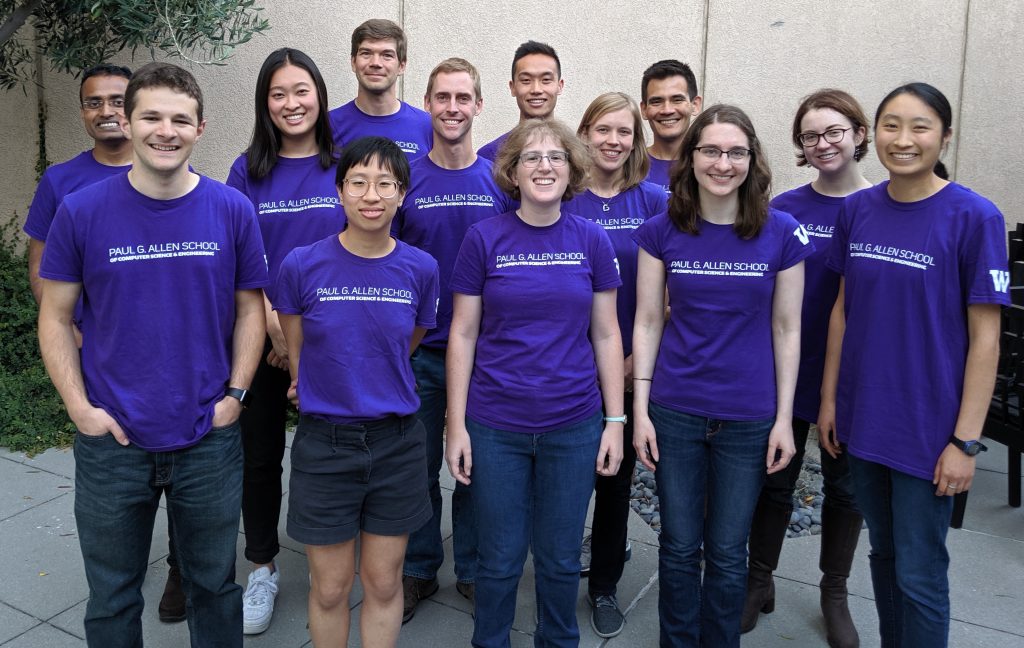
While at USENIX Security 2019, we were fortunate to snap a photo of a significant fraction of the current Security Lab as well as Security Lab and other alumni wearing our purple Allen School shirts!
What makes Grover so effective at spotting fake news is the fact that it was trained to generate fake news itself.
When we hear the term “fake news,” more often than not it refers to false narratives written by people to distort the truth and poison the public discourse. But new developments in natural language generation have raised the prospect of a new potential threat: neural fake news. Generated by artificial intelligence and capable of adopting the particular language and tone of popular publications, this brand of fake news could pose an even greater problem for society due to its ability to emulate legitimate news sources at a massive scale. To fight the emerging threat of fake news authored by AI, a team of researchers at the Allen School and Allen Institute for Artificial Intelligence (AI2) developed Grover, a new model for detecting neural fake news more reliably than existing technologies can.
Until now, the best discriminators could correctly distinguish between real, human-generated news content and AI-generated fake news 73% of the time; using Grover, the rate of accuracy rises to 92%. What makes Grover so effective at spotting fake content is that it learned to be very good at producing that content itself. Given a sample headline, Grover can generate an entire news article written in the style of a legitimate news outlet. In an experiment, the researchers found that the system can also generate propaganda stories in such a way that readers rated them more trustworthy than the original, human-generated versions.
“Our work on Grover demonstrates that the best models for detecting disinformation are the best models at generating it,” explained Yejin Choi, a professor in the Allen School’s Natural Language Processing group and a researcher at AI2. “The fact that participants in our study found Grover’s fake news stories to be more trustworthy than the ones written by their fellow humans illustrates how far natural language generation has evolved — and why we need to try and get ahead of this threat.”
Choi and her collaborators — Allen School Ph.D. students Rowan Zellers, Ari Holtzman, and Hannah Rashkin; postdoctoral researcher Yonatan Bisk; professor and AI2 researcher Ali Farhadi; and professor Franziska Roesner — describe their results in detail in a paper recently published on the preprint site arXiv.org. Although they show that Grover is capable of emulating the style of a particular outlet and even writer — for example, one of the Grover-generated fake news pieces included in the paper is modeled on the writing of columnist Paul Krugman of The New York Times — the researchers point out that even the best examples of neural fake news are still based on learned style and tone, rather than a true understanding of language and the world. So, that Krugman piece and others like it will contain evidence of the true source of the content.
“Despite how fluid the writing may appear, articles written by Grover and other neural language generators contain unique artifacts or quirks of language that give away their machine origin,” explained Zellers, lead author of the paper. “It’s akin to a signature or watermark left behind by neural text generators. Grover knows to look for these artifacts, which is what makes it so effective at picking out the stories that were created by AI.”
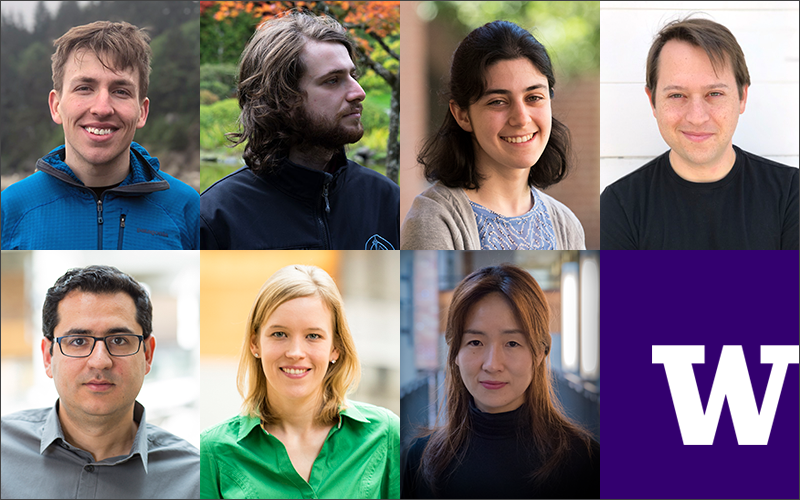
The research team, top row from left: Rowan Zellers, Ari Holtzman, Hannah Rashkin, and Yonatan Bisk. Bottom row from left: Ali Farhadi, Franziska Roesner, and Yejin Choi.
Although Grover will naturally recognize its own quirks, which explains the high success rate in the team’s study, the ability to detect evidence of AI-generated fake news is not limited to its own content. Grover is better at detecting fake news written by both human and machine than any system that came before it, in large part because it is more advanced than any neural language model that came before. The researchers believe that their work on Grover is only the first step in developing effective defenses against the machine-learning equivalent of a supermarket tabloid. They plan to release two of their models, Grover-Base and Grover-Large, to the public, and to make the Grover-Mega model and accompanying dataset available to researchers upon request. By sharing the results of this work, the team aims to encourage further discussion and technical innovation around how to counteract neural fake news.
According to Roesner, who co-directs the Allen School’s Security and Privacy Research Laboratory, the team’s approach is a common one in the computer security field: try to determine what adversaries might do and the capabilities they may have, and then develop and test effective defenses. “With recent advances in AI, we should assume that adversaries will develop and use these new capabilities — if they aren’t already,” she explained. “Neural fake news will only get easier and cheaper and better regardless of whether we study it, so Grover is an important step forward in enabling the broader research community to fully understand the threat and to defend the integrity of our public discourse.”
Roesner, Choi and their colleagues believe that models like Grover should be put to practical use in the fight against fake news. Just as sites like YouTube rely on deep neural networks to scan videos and flag those containing illicit content, a platform could employ an ensemble of deep generative models like Grover to analyze text and flag articles that appear to be AI-generated disinformation.
“People want to be able to trust their own eyes when it comes to determining who and what to believe, but it is getting more and more difficult to separate real from fake when it comes to the content we consume online,” Choi said. “As AI becomes more sophisticated, a tool like Grover could be the best defense we have against a proliferation of AI-generated fake news.”